WRLD

Search

#benchmarks
Jordan Bardella 6d

The author wrote that the release of Mistral Large 4, nicknamed "Le Chonk," had put France and Europe back in the race for artificial intelligence. He noted that initial benchmarks placed the model on par with the best open Chinese models and described this news as excellent for France. #IntelligenceArtificielle #MistralAI #Innovation #FR #CN (translated)
3391
RobynHD Sep 3

🚨 OpenAI hat gerade GPT-6 Astra vorgestellt und die ersten Ergebnisse sind extrem. Laut veröffentlichten bzw. derzeit kursierenden Benchmarks erreicht Astra unter anderem: • ARC-AGI-3: 98,6% • ExploitBench: 100% • SRE-Bench: 99,2% • AutomationBench: 41,4% Zum Vergleich: GPT-5.6 Sol kam beim ARC-AGI-3 offiziell auf gerade einmal 7,78% und beim AutomationBench auf 18,1%. Die 100% beim ExploitBench werden von OpenAI selbst bestätigt. Astra ist zudem das erste OpenAI-Modell, das beim Cybersecurity-Risiko die Stufe „Critical“ erreicht. OpenAI zufolge konnte es in Tests sogar bislang unbekannte Sicherheitslücken finden und Exploit-Ketten entwickeln. Wichtig: Die spektakulären 98,6% beim ARC-AGI-3 konnte ich bislang nicht auf einer offiziellen OpenAI-Seite verifizieren. Der Wert sollte daher noch mit Vorsicht betrachtet werden. Unabhängig davon spricht OpenAI-Präsident Greg Brockman beim neuen Modell bereits vom Beginn der „AGI-Ära“. #OpenAI #GPT6 #KI

11807
Gedas Bertasius Jul 23

Our proposed VideoTreeSearch achieves state-of-the-art results across all grounded long-video QA benchmarks while also being more efficient than prior agentic video methods. We also show that we can achieve strong temporal grounding results even if we don't use any manually #VideoTreeSearch #LongVideoQA #AI #Nocountrycodesarementionedinthetweet.

marcus Jul 16

MOONSHOT ACABA DE LANZAR EL MODELO OPEN SOURCE MÁS GRANDE DE LA HISTORIA se llama Kimi K3. 2.8 billones de parámetros. ventana de contexto de 1 millón de tokens. multimodal nativo. lo interesante no es solo el tamaño. usa dos arquitecturas nuevas: Kimi Delta Attention y Attention Residuals. → decodificación hasta 6.3x más rápida en contextos de 1M tokens → ~25% más eficiencia de entrenamiento con menos de un 2% de coste extra → pensado para coding de largo horizonte y trabajo agéntico según los propios benchmarks de Moonshot, K3 solo queda por detrás de Claude Fable 5 y GPT-5.6 Sol. y por delante de Claude Opus 4.8. todo open source. #OpenSource #AI #MachineLearning

12211
Adam Jarubas Jul 16

Reforma systemu ETS jest absolutnie potrzebna dla odbudowy konkurencyjności przemysłu polskiego i europejskiego. Będę zajmował się jedną z kluczowych regulacji w tym obszarze. W piątek zostanie opublikowana propozycja @EU_Commission i zaczynamy. #przemysł #emisje #ETS #benchmarks #emisje #ETS #przemysł #PL #EU

237
Plattenbauaristokrat Jul 2

Ich finde, es sollte in Deutschland eine Möglichkeit geben, die Kinder neben den klassischen Schulen zu Hause zu unterrichten. Wenn sie dann staatliche Tests absolvieren und die geforderten Leistungen regelmäßig erreichen, sollten die Eltern pro Kind 12.000 € im Jahr steuerfrei erhalten. Der Staat gibt laut Statistischem Bundesamt sowieso diese Summe pro Schüler aus. Warum also nicht den Eltern überlassen, wie sie das Geld einsetzen, solange das Kind die Benchmarks erreicht? #Bildung #Homeschooling #Steuern

12599
antirez Jun 17

OpenAI may delay GPT6 (or even 5.6) before making sure could not be blocked like Fable. Or they could play it smart, publishing only the benchmarks that show the improvements on certain area, providing a very censored model in the cyber-security side, and cross their fingers. #OpenAI #GPT6 #CyberSecurity #Nospecificcountrycodesarepresentinthetweet.

238
Christophe Barraud🛢🐳 Jun 13

🇨🇳🇺🇸 The most important AI leaderboard today isn't benchmarks. It's adoption. #OpenRouter's rankings show a striking trend: Chinese models are rapidly overtaking US models in real-world developer usage ⚠ Models from DeepSeek, Kimi, MiniMax, GLM, and Qwen now account for a large https://t.co/H2dYoBiWQ4 #AI #China #TechTrends #CN #US

358
antirez May 28

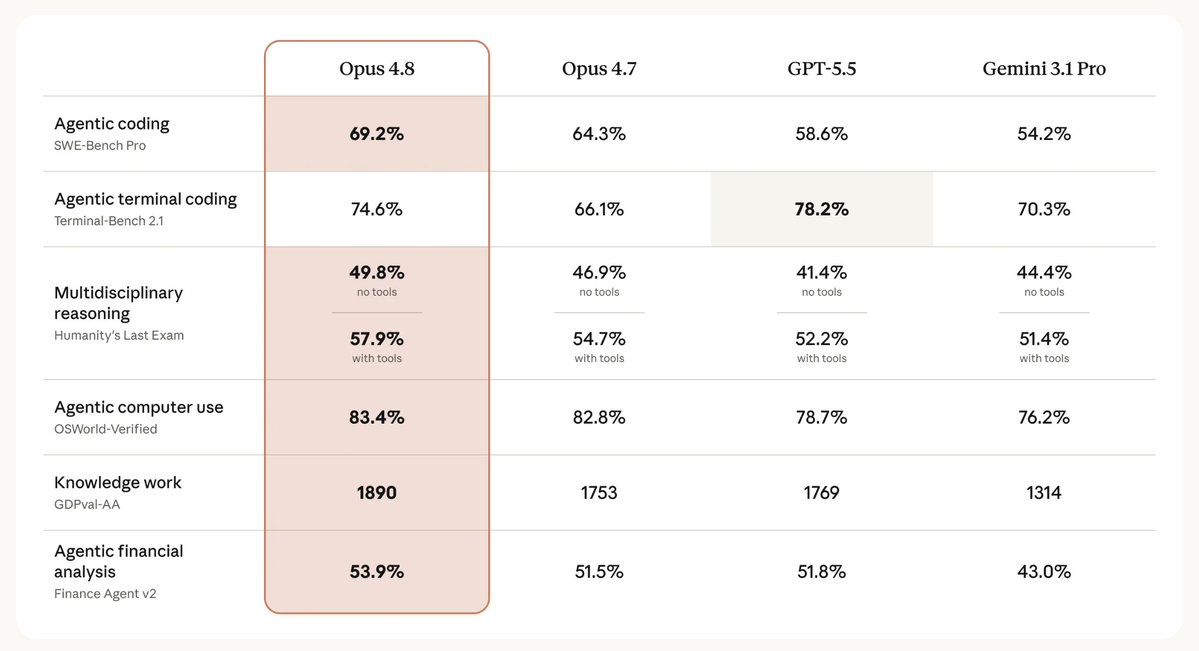
Anthropic did a big strategic error. Normally they compare their models with their old models. Instead today, now that everybody knows how strong GPT 5.5 is at coding, they put it in the mix, basically showing all their customers that the benchmarks can't be trusted. https://t.co/up73bHAfen #AI #Anthropic #GPT5.5 #Therearenospecificcountrycodesrelatedtothecontentofthetweet.

www.diepresse.com
Friedrich Merz richtet dramatischen Appell an die Deutschen: „Es geht um unsere demokratische Zukunft“ [premium]
478
Marta Kos May 26

A big step forward for Albania on its path to EU membership! With Albanian Prime Minister @ediramaal and Cypriot Deputy Minister for European Affairs @marilena_raouna in Brussels today, Albania reached the interim benchmarks, and we set the closing benchmarks for fundamentals https://t.co/oyf8mftyn7 #Albania #EUMembership #BrusselsSummit #AL #CY

1434
Yann LeCun May 14

RT @logic_int: Aleph, our fully autonomous AI agent system for formal verification, aced all major theorem proving benchmarks including Put… #AI #AutonomousSystems #FormalVerification #Nospecificcountriesarementionedinthetweet.